

Abstract
Artificial intelligence now outperforms humans in several scientific and engineering tasks, yet its internal representations often remain opaque. In this Perspective, we argue that explainable artificial intelligence (XAI), used alongside causal reasoning and domain validation, enables learning from the learners. Focusing on discovery, optimization and certification, we show how foundation models and explainability methods can expose model-internal decision processes, generate candidate mechanistic hypotheses, guide robust design and control, and support trust and accountability in high-stakes applications.
Subjects
- Computational science
- Computer science
- Mechanical engineering
Introduction
Scientific progress has long depended on building interpretable models of complex systems, from Newton’s laws to the Navier–Stokes equations, which encode mechanistic understanding and enable prediction, control and design. In recent years, however, machine learning (ML) has begun to transform this paradigm. Deep neural networks can now infer relationships in high-dimensional data that are inaccessible to classical theory, often matching or surpassing human experts in tasks ranging from protein folding1 to turbulence control2. This new reality raises a profound question: if machines can learn representations of physical systems that outperform human models, can we, in turn, learn from the learners? Addressing this question requires explainable artificial intelligence (XAI)3: a suite of methods that make the internal logic of ML systems interpretable to human reasoning. We use the term XAI in a broad scientific-ML sense, while distinguishing canonical XAI methods from adjacent interpretable modeling tools. In the narrower sense, XAI includes methods such as feature attribution, counterfactual explanations, data attribution and mechanistic interpretability. In this Perspective, we also discuss interpretable scientific-ML and representation-learning tools, such as symbolic regression, operator learning and autoencoders, because they can make learned models or latent representations more accessible to scientific interpretation. These tools are not all XAI methods in the strict post-hoc or mechanistic sense, but they form part of a broader explainability workflow for scientific discovery, optimization and certification. Throughout this Perspective, we distinguish between model-level explanations and system-level causal claims. XAI methods are, by themselves, informative about an AI model: they describe how inputs, learned representations, or internal components influence the predictions or decisions of the model. They do not, on their own, establish causal relationships associated with the physical system being modeled. System-level causal claims require additional assumptions and evidence, including representative data, validated physical constraints or governing models where available, robustness under distribution shift, and, ideally, targeted numerical or physical interventions. We therefore use XAI primarily as a tool for generating, organizing and testing mechanistic hypotheses; causal interpretations become credible only when the learned model is sufficiently faithful to the system, and the proposed mechanisms survive independent validation.
Explanations have always been central to scientific inquiry: they connect abstract models to causal understanding and experimental validation. In modern deep learning, however, the representations learned by a model are rarely transparent4. XAI thus provides an interface between machine predictions and human understanding, allowing researchers to inspect which features drive the decisions of a model, estimate their influence on model outputs and assess whether these model-level patterns are consistent with physically meaningful mechanisms.
The connection between model explainability and causal reasoning5,6,7 is particularly relevant for science and engineering, provided the distinction above is maintained. Causality formalizes the notion of intervention and is therefore central to scientific reasoning8,9. Recent developments in causal inference and information theory allow decomposition of causal effects into unique, redundant and synergistic components10, enabling a more granular view of how different variables contribute to an outcome under specified assumptions. Such tools can help distinguish candidate mechanisms from spurious correlations in complex datasets. When combined with XAI techniques such as SHapley Additive exPlanations (SHAP)3 or integrated gradients11, they can support a mechanistic interpretation of deep-learning models: which regions of a flow field, which frequencies in a spectrum or which molecular configurations are most influential for a predicted outcome. This model-level evidence can motivate hypotheses about physical mechanisms, but those hypotheses require validation before being treated as causal claims about the underlying system. This explainability-and-validation workflow opens new opportunities to generate and test candidate scientific laws from data-driven systems.
A key point in this context is generalizability. Models that are fully explainable in a narrow domain but fail when extrapolated to new conditions provide limited scientific insight. Explainability, therefore, complements generalization: only by identifying the underlying mechanisms can one predict the behavior under unseen parameters.
This connection between causality and generalization has been formalized in the invariance-based causal inference literature12,13,14,15,16. A central insight is that causal models are inherently more robust to distribution shifts because they capture stable mechanisms rather than environment-specific correlations, a principle recently extended to the broader trustworthy-AI landscape by Binkyte et al.17. To this end, if XAI methods can reveal whether a learned model relies on such invariant causal features, they offer a diagnostic pathway for assessing generalization and trustworthiness, complementing the information-theoretic causal decomposition discussed later in this Perspective.
Explainability may also play a decisive role in identifying the mechanisms behind extreme events. These rare but high-impact occurrences (e.g., extreme weather or structural failures) are often underrepresented in the training datasets and are thus poorly captured by statistical models. Indeed, AI models tend to overfit frequent regimes while missing rare ones18,19. XAI methods can help identify subtle model-relevant precursors to such events and, when combined with causal analysis and validation, support the distinction between potentially causal pathways and correlations. As with all model-level explanations, the reliability of such analyses depends on whether the model has sufficiently learned the relevant dynamics. Rare events are typically underrepresented in training data, hence explanations may reflect artifacts of the model’s approximation, reinforcing the need for independent validation before interpreting them as physically meaningful.
Recent advances in self-supervised learning and diffusion models20 further expand the scope of explainability. These approaches learn by context rather than explicit supervision, discovering the statistical structure of their environment. By embedding physics into such architectures (through inductive biases, conservation constraints or equivariance principles), these models can capture the latent organization of complex systems. Yet, the more powerful these models become, the more opaque their internal reasoning tends to be. Interpretable training signals, causal priors and physically meaningful embeddings are therefore essential for ensuring that generalization arises from the identified mechanisms and not by coincidence.
It is also essential to note that explainability can be illusory. Not every attribution map or saliency pattern constitutes a true explanation. Post-hoc justifications (especially those mimicking human reasoning) can create a false sense of understanding. Anthropomorphic metaphors (e.g., describing networks as attending or reasoning) may obscure what a model actually computes21,22. Thus, explainability itself must be subjected to rigorous validation23, with metrics for faithfulness and stability ensuring that explanations reflect the computations of the model. Note that any system-level causal interpretation must then be evaluated separately through domain-specific validation24,25,26,27.
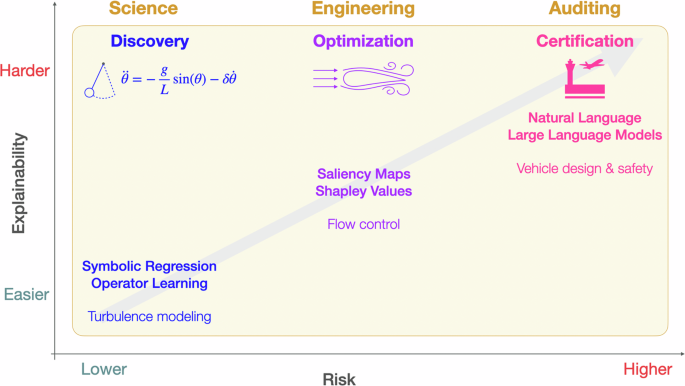
In this Perspective, we argue that explainable AI offers not just interpretive insight but a framework for scientific collaboration between humans and machines. As summarized in Fig. 1, we focus on three domains: discovery, optimization and certification, which are connected with science, engineering and auditing28. In discovery, XAI aids in exposing model-internal structure, generating testable hypotheses about mechanisms and uncovering governing equations from data. In optimization, it guides design and control by revealing which parameters, mechanisms or spatial regions drive performance. And in certification, it achieves trust and accountability, allowing automated systems to be audited and aligned with human values. These domains are tightly coupled: insights discovered through explainable models inform optimization strategies, and the interpretability required for certification constrains how discoveries are validated and deployed. Explainability thus acts as the link between data-driven learning, mechanistic understanding and ethical governance.
Deep learning has paradoxically expanded both the opacity and the potential of scientific models. While black-box architectures outperform interpretable surrogates, they also contain within them rich representations of physical phenomena (see Fig. 2). If extracted properly29, these representations may reveal new principles (similarly to how symbolic-regression methods30 distilled empirical laws from data), but now at a scale spanning billions of parameters and multidimensional manifolds31. Explainable AI provides the tools for this extraction, translating machine-learned representations into human knowledge. As the boundaries between simulation, optimization and automated reasoning blur, the ability to interpret how machines learn will determine whether artificial intelligence becomes a scientific collaborator or merely a computational tool.
Ultimately, learning from the learners requires more than decoding predictions: it involves understanding the underlying reasoning processes. XAI may have the potential to help turn data-driven models into engines of discovery and control that not only predict but also generate testable explanations by carefully linking causal reasoning, interpretability and generalization. This long-term goal will inherently be a human-AI collaboration for the foreseeable future. The following sections explore how this vision unfolds across the three core domains, each bringing distinct challenges and converging towards a shared goal: a new form of science in which humans and machines co-create understanding.
This Perspective offers several contributions. We frame discovery, optimization and certification as a connected continuum in which shared explainability and causal-reasoning principles transfer across domains. We introduce a systematic distinction between model-level explanations and system-level causal claims and apply it to qualify the role of XAI throughout the scientific workflow. We delineate the scope of XAI in a scientific-ML context, distinguishing canonical post-hoc methods from other interpretable modeling tools. We propose an original explainability-oriented framework (Fig. 3) that integrates foundation models, latent-space causal analysis, physical-space attribution and agentic AI for autonomous scientific discovery and design. Finally, we outline a certification framework (Fig. 4) based on trust by understanding rather than trust by performance. These elements build on relatively established research areas, but here we take the view of how these integrate together for scientific and engineering practice.
Explainable AI for discovery
There is tremendous potential for AI to drive progress in scientific discovery, with examples already emerging in fields as diverse as molecular biology1,32,33, fusion34, astrophysics35,36,37, and fluid dynamics38,39,40. It is likely that the future of science will involve an even deeper collaboration between humans and AI agents. However, many of our most powerful deep-learning architectures are opaque and do not readily provide insights into how outcomes and predictions are generated. This opacity is in tension with the scientific method22, which requires detailed explanations, mechanistic hypotheses and validation, thereby providing the ability to justify conclusions, verify results and design new hypotheses to be tested. If we aim to remain active participants in this collaboration, we must not only seek models with the highest prediction accuracy, but also design models that expose simple, explainable and testable candidate mechanisms.
Fortunately, there are several techniques that help provide the explainability required for AI agents to work collaboratively with human scientists. Explainability in a scientific context often relies on identifying parsimonious model structures or mechanistic hypotheses, meaning that they are as simple as required to describe the data and cannot be made simpler. Parsimonious models tend to be more interpretable by design and more generalizable, as they discourage overfitting and distill the key underlying mechanisms of a system. This principle of parsimony, also known as Occam’s razor, has been the gold standard in physics for 2000 years, from Aristotle to Einstein, and it is unlikely that this paradigm will be upended in a few decades of AI research.
Of course, we hope that AI agents will uncover correlations and mechanisms that are more sophisticated than humans are able to explore directly. However, complexity is not incompatible with explainability, provided the explanations are composable in terms of simpler concepts. Many complex systems are understood through sequences of individually explainable steps, even when the overall system requires substantial expertise to master, such as operating a nuclear reactor or assembling an aircraft. In scientific discovery, we therefore often accept a reduction in immediate descriptive completeness in exchange for models that expose fundamental and generalizable mechanisms. Kepler’s elliptical orbits, for instance, replaced the flexible epicyclic machinery of Ptolemaic astronomy with a more constrained geometric structure. Although this model did not capture the full complexity of the observed data, it revealed a simpler and more generalizable organization of planetary motion that later became central to Newtonian mechanics. Similarly, Galileo’s idealized treatment of falling bodies abstracted away many features of real motion, including wind resistance, vortex shedding, and object shape, among other effects. Its value was not that it described every falling object more accurately in every circumstance, but that it isolated a robust, underlying principle: in the absence of complicating effects, bodies share a common gravitational acceleration. Once this idealized mechanism was identified, additional physics, such as drag, could be incorporated systematically. Of course, there are systems where oversimplified models sacrifice too much physical accuracy and are fundamentally incorrect. In practice, it is often necessary to identify a hierarchy of candidate models of increasing complexity, and then design targeted experiments to disambiguate between different mechanisms. That said, parsimony is still essential to prevent overfitting in this model selection procedure.
There are several techniques at our disposal to promote parsimonious, and hence explainable, AI models. Sparsity and low-dimensionality have long been used in machine learning to prevent overfitting and constrain models toward representations that isolate the essential degrees of freedom of a system. By limiting the number of active variables or latent dimensions, these approaches often support interpretability even when the underlying implementations are complex. Sparse symbolic regression provides a particularly clear path towards parsimonious models, as the explicit objective is to discover simple equations that describe the data or the function learned by a model. It is important, however, to add the caveat that there are classes of complex systems where the underlying dynamics are not easily reducible to simple, sparse or low-dimensional representations. In these cases, it may be possible to learn coordinate systems in which the dynamics simplify (e.g., the Copernican coordinate system enabled classical mechanics), although there are many cases where simplifying coordinate systems have been elusive (e.g., turbulence closure modeling).
Symbolic regression is a particularly useful technique in machine learning for scientific discovery, resulting in models that take the form of parsimonious symbolic expressions. These models are often more interpretable to humans, as they can expose explicit relationships among variables. When supported by interventions, physical constraints or independent validation, these relationships may support stronger causal hypotheses. Today, there are two main approaches to symbolic regression: genetic programming to grow function trees compositionally, and sparse regression in a library of candidate terms. These approaches are complementary, operating in different regimes of expressivity, data efficiency, and computational cost41. In the following, we will briefly review each approach and highlight how they have been useful in explainable AI-enabled scientific discovery.
Genetic programming (GP) grows increasingly sophisticated function expressions through the composition of simpler basis functions, such as addition, multiplication, trigonometric functions, and other elementary operations. Although GP was widely used for decades, it became a powerful tool for parsimonious scientific discovery in the work of Bongard and Lipson42 and Schmidt and Lipson43. A key contribution of this work was its emphasis on the importance of parsimony in symbolic learning, using the Pareto frontier of model complexity versus accuracy to identify expressions that are both simple and descriptive. In the intervening years, great strides have been made30,44,45,46, with PySR30 emerging as a powerful general-purpose tool for symbolic regression in scientific discovery.
More recently, sparse regression has emerged as a particularly effective technique for parsimonious symbolic regression in scientific discovery29. The sparse identification of nonlinear dynamics (SINDy) algorithm identifies the fewest terms in a library of candidate functions needed to describe a given system, typically the right-hand side of a differential equation. By construction, these models have relatively few parameters, making them data efficient and contributing directly to their interpretability and generalizability. SINDy is particularly extensible because it is based on generalized linear regression in a library of nonlinear functions, with variants that incorporate actuation and control47. Importantly for scientific discovery, it is possible to enforce symmetries and constraints derived from known physics39, such as energy conservation in incompressible fluids, which in turn makes it possible to guarantee model stability48. The dual perspective is to learn what symmetries are present in a dataset or model, providing an additional and powerful form of physical explainability49.
One of the most important applications of sparse symbolic regression for scientific discovery is its extension to partial differential equations (PDEs)50,51. By augmenting the library with partial derivatives, it is possible to learn a sparse representation of the governing PDE directly from data. While this approach is generally sensitive to noise, it has been augmented with the weak formulation52,53 and ensemble learning54 to dramatically improve noise robustness. These advances have enabled the discovery of entirely new, interpretable physics models in domains including closure modeling for turbulent fluids55,56,57, plasmas58, Galerkin models39, active matter59, and geophysical flows60. Other symbolic approaches for PDE learning have also shown promise61.
Closely related to discovering parsimonious models of system dynamics is the importance of identifying effective coordinate systems in which to represent the dynamics. Many major scientific breakthroughs were preceded by the discovery of appropriate coordinates; for example, the Copernican model, which placed the sun at the center of our solar system, directly enabled the discovery of Kepler’s laws of planetary motion. One of the great strengths of modern AI systems is their ability to digest vast quantities of data and uncover dominant, actionable patterns, making them well-suited for discovering such coordinates. This has made the autoencoder (AE)62,63,64,65,66,67 an important representation-learning tool for mechanistic interpretability and explainability-oriented scientific ML. Autoencoders operate by reconstructing input data while imposing an information bottleneck, typically through a low-dimensional latent space, forcing high-dimensional data to be distilled into a small number of coordinates. In this sense, AEs may be viewed as a nonlinear generalization of the singular value decomposition (SVD), which is itself a data-driven generalization of the Fourier transform68. Autoencoders have therefore been widely used to support interpretability in scientific machine learning, for example, by promoting sparse models in SINDy64,69 or by identifying coordinates that enable more stringent assumptions, such as strictly linear latent dynamics63,70,71,72,73,74. In this role, AEs are not post-hoc or mechanistic XAI methods: instead, they provide latent representations that can become interpretable when constrained, disentangled or connected to explicit physical variables or governing equations. The question of when latent representations can be identified with true causal variables is formalized in the field of causal representation learning16. Unsupervised disentanglement is generally not identifiable without additional structure75, but identifiability can be recovered under weak supervision, known interventions or temporal structure76,77. In the scientific ML context of this Perspective, physical constraints, symmetries and governing equations play an analogous role, as they provide inductive biases that help constrain latent representations toward physically and potentially causally meaningful variables. Even when the network implementation is complex, the explicit identification of a low-dimensional latent space provides a meaningful and interpretable representation. Further, Cranmer et al.78 introduced the notion of disentangled sparsity to derive symbolic expressions for each of the latent variables in terms of a sparse subset of the high-dimensional input variables.
A complementary form of explainability in AI-enabled scientific discovery arises from restricting models to represent specific physical functions or mechanisms. We have already seen this in the example of turbulence closure modeling, where the focus is put on modeling a specific physical mechanism, such as the Reynolds stresses38. Regardless of the internal complexity of the model, if its purpose is tightly constrained to a well-defined physical concept, then explainability is embedded in the function that the model is designed to represent. This perspective has been particularly influential in computational chemistry32,79, for example, through the use of free energy and related concepts to impose physical meaning on deep learning models79. Related examples include Lagrangian and Hamiltonian neural networks80,81, which leverage deep learning to represent fundamental physical functions with clear interpretations. Incorporating symmetries into learning architectures is also used to improve generalization and embed deeply intuitive physical principles into otherwise opaque models39,49,82,83,84,85. More broadly, scientific explainability has often been bootstrapped by identifying and naming recurring functional structures. For example, the Bessel functions are defined by recursion relations to solve classes of differential equations that occur frequently in science and engineering, providing a compact and interpretable abstraction for otherwise complex behavior.
Explainable AI for optimization
Optimization problems in science and engineering increasingly rely on machine-learning (ML) models with predictive86,87 and control88,89 capabilities exceeding those of traditional approaches. However, exploiting these models for design or real-time control requires understanding why they make certain decisions and which variables or regions of the system drive those outcomes. Explainable artificial intelligence (XAI)3,90 therefore plays a central role in obtaining this type of insight, enabling both improved performance and deeper physical understanding. Classical optimization methods typically rely on gradient-based sensitivity analysis91 or adjoint methods92 to identify influential parameters. In contrast, modern ML models (especially deep neural networks) require explainability techniques adapted to high-dimensional regression and classification tasks. The SHapley Additive exPlanation (SHAP)93 framework, with its theoretical foundation in cooperative game theory, has become a cornerstone of post-hoc attribution methods for complex models. Kernel SHAP3 provides a flexible (although computationally expensive) approximation, while gradient-based SHAP90 offers scalability by exploiting backpropagation. Other relevant XAI methods are integrated gradients11 and saliency maps94. In the context of engineering optimization, these methods reveal which input features most strongly influence the optimization objective, from aerodynamic performance to energy efficiency. They have been successfully applied across fluid mechanics7,95, heat transfer96, combustion97 and renewable-energy applications98, among others. Such analyses can clarify model-internal patterns that align with known physical mechanisms and highlight potential strategies for improving designs and controlling systems beyond what the model itself proposes.
A recurring challenge is that high-performing ML models may learn representations that are highly efficient for the machine, yet unintuitive for humans. For example, deep reinforcement learning2,99 or diffusion-based design models100 often solve a control or optimization task in latent spaces that compress the dynamics into low-dimensional manifolds. While such manifolds are computationally advantageous, they obscure the physical mechanisms underlying the solution. Here, explainability offers a mechanism for translating between the internal representation of the machine and the human-understandable physical space. Gradient-based SHAP90 is particularly valuable because it can be computed at extremely high resolution, scaling to hundreds of millions of spatial points in parallel. This makes it possible to identify model-attributed importance in the physical flow domain7, even when the underlying network operates in a latent space. Consequently, SHAP-based explanations can invert the abstraction introduced by representation learning, mapping the compressed reasoning of the machine back into interpretable physical structures, such as coherent vortical regions, thermal layers, reactive fronts or stress concentrations7,95. This dual-space interpretability is essential in engineering, where optimization outcomes must ultimately translate into physical actions: changes to geometry, actuation or boundary conditions. Connecting latent-space decision making with physical-space mechanisms enables domain experts to validate, generalize and build upon machine-generated solutions. An example is the use of gradient SHAP to guide flow control based on deep reinforcement learning: SHAP identifies the turbulent-flow structures that are most influential for the model, and these structures can then be used to shape the DRL reward, yielding an effective flow-control strategy101. In fact, taking the example of drag reduction, it has been shown101 that using drag minimization as the reward is less effective than minimizing the physical mechanisms responsible for the drag, as the latter tackles the root rather than the symptom. This principle has been extended to other optimization problems102, with key implications in science103 and engineering104.
Optimization is inherently intervention-oriented: improving a design requires understanding which changes are expected to produce which effects. For this reason, optimization benefits from causal reasoning, provided that causal claims are interpreted relative to the model and then validated in the physical system. Note that the SURD (synergistic, unique and redundant decomposition) framework10 mentioned above provides a richer decomposition of causal interactions, but computing SURD or related causal decompositions in physical space is prohibitively expensive for high-dimensional systems. To address this, causal inference is often performed in a latent space, where the dynamics are encoded as multivariate time series. Autoencoders63,105, β-variational autoencoders (β-VAEs)62,87,106 or other manifold-learning architectures naturally produce such representations. Within these manifolds, SURD can estimate candidate causal structures governing the evolution of the learned representation or the optimization objective, under the assumptions of the causal model. This causal structure then guides principled intervention strategies, for example, identifying the specific latent directions that correspond to beneficial actuation paths, or the synergies between flow regions responsible for drag reduction. When combined with SHAP-based reconstructions in physical space, this creates a useful model-analysis framework: candidate causal relations are estimated in the latent manifold and then related to physical structures107, producing hypotheses that can be tested and potentially exploited for control.
Beyond attribution, gradient SHAP can act as a form of causal dimensionality reduction. Instead of compressing the system into a latent space, SHAP can reweigh the physical points of the domain according to their importance for a given task7. This preserves interpretability and maintains direct correspondence with actuators, which naturally operate in physical coordinates. By pruning the domain to only the most important points, one can build reduced-order models or controllers that focus exclusively on the dynamically relevant structures. This creates an alternative to latent-space modeling, which is interpretable and physically grounded. Then, the SHAP-identified features may serve as a compressed but physically meaningful basis for reconstruction or closed-loop control101. This physical-space dimensionality reduction is particularly appealing for engineering systems where actuation is spatially localized: SHAP highlights precisely those regions where interventions are most effective, enabling energy-efficient and robust optimization strategies. Thus, integrating explainability into optimization closes the loop between discovery and action: ML models propose an optimized solution or control policy, often identified in a latent space. Causal analysis can indicate how the model represents the emergence of a solution, pinpointing interactions that may drive improvements and should be validated through targeted simulations, experiments or control interventions. Gradient-based SHAP represents these interactions in the physical space, producing interpretable attribution fields. Engineers can use these insights to design or refine actuation mechanisms, validate the reasoning of the model or generalize to new conditions. Then the system becomes safer, more transparent and more robust, particularly when optimization interacts with complex physics. Representative examples of this explainability-oriented optimization loop can be found across several engineering domains. In aerodynamic shape optimization, SHAP-based attributions have been mapped from geometric design variables to surface regions to expose objective trade-offs104. In turbulent-flow control, SHAP-identified model-relevant flow structures have been used to construct DRL rewards for improved control strategies101. In structural engineering, SHAP has been used to interpret load-deformation predictions for long-span bridges108. In heat-transfer and thermal-energy systems, ML-based sensitivity and attribution analyses have identified influential geometric and operating parameters96,98. In reactive-flow and combustion modeling, interpretable ML methods have been used to analyze and construct data-driven closure models109. These examples do not imply that an identical pipeline has been fully demonstrated in every engineering field, but they illustrate how the same workflow can be transferred to multiphysics applications when attribution, latent-space analysis and domain validation are defined for the relevant coupled fields. Such a workflow preserves the speed, flexibility and nonlinearity of ML-driven optimization while adding interpretable diagnostics and validation methods.
Explainable AI is emerging both as a diagnostic tool and a method for optimization and physical understanding. A possible framework for this is illustrated in Fig. 3, exemplified by a fluid-mechanics problem: data from different flow cases (wings, cities…) and flow conditions (Reynolds number, Mach number, flow orientation…) are first represented in a shared latent dynamical space. A β-VAE87 encodes each instantaneous flow field into a low-dimensional latent vector, while a transformer110 acts as the temporal sequence model, predicting the evolution of these latent vectors from previous latent states and the relevant conditioning parameters. Then, conditional latent diffusion86,100 is used to learn the distribution of the different slices of the latent space, potentially generalizing to new (unseen) conditions (wind turbines, drones…) as long as a good parameterization across geometries is found. This foundation model111 can be used as an engine for discovery by an agentic-AI system based on large language models (LLMs)112,113. Note that such foundation models have been proposed for discovery in chemistry114 and LLMs are being used for automated design optimization115. Such a system may use one slice of the latent space to understand dynamic mechanisms for a particular flow configuration based on causal analysis10, and decide the next conditions to explore by defining new parameters and generating new latent spaces that can be decoded into a physical space, producing new relevant phenomena in that new configuration. SHAP can be key in this context, since it can connect regions of the physical space for certain system conditions with concrete latent representations. Thus, an agentic AI system that may reach scientific understanding for optimization in a latent space can be made interpretable in physical space through SHAP, which will enable connecting known physical phenomena with the physics newly discovered in the latent space. In summary, foundation models combined with XAI can help to reduce the complexity of a problem, enabling a more efficient optimization.
Explainable AI for certification
ML models are increasingly embedded into high-stakes scientific, engineering and social workflows, from climate prediction and natural-hazard early warning to structural health monitoring, aerospace design, offshore energy systems, autonomous robotics, healthcare, and finance. As these AI-augmented systems transition from research prototypes to operational decision tools, a central question lies in how we certify that these models are trustworthy and safe for deployment. The response to this question has critical implications for liability: should the AI-augmented system fail and create significant damages to the affected entity, who should pay the price?
Traditional validation pipelines involve extensive testing prior to adoption and deployment. For instance, an aircraft would need to go through extensive ground-based testing of each component and flight tests prior to entering into service. The on-board computers will also require extensive testing under various operating conditions to guarantee that fly-by-wire is safe and does not behave unexpectedly (failure in this realm can produce catastrophic consequences, e.g., ref. 116). Similarly, a medical doctor will need to undergo extensive specialized training before being able to practice and make decisions on a patient’s well-being. When an aircraft fails or a medical doctor makes a wrong decision, the liability chain is relatively clear, albeit not always. This is because there are protocols in place to certify and audit what went wrong. In fact, many of these more traditional workflows tend to behave with deterministic causality: a failure takes place, and we can walk backward to understand the steps that led to this failure. Obviously, this is not always the case: certain systems are inherently random (e.g., the financial markets). In these cases, a degree of failure is disclosed a-priori and is expected. However, in engineering and healthcare applications, such tolerance to failure is vastly reduced, and there are mechanisms in place to prevent catastrophic outcomes (or at least understand why they eventually happened).
If we are now deploying AI-augmented solutions to some of these failure-averse fields, such as engineering and medicine, what are the guardrails (if any) that we want to have in place to certify a given ML solution, and audit it in case of failure?
ML systems are statistical tools with a certain degree of randomness, whereby data distribution shifts and out-of-distribution data points can cause them to fail, or at least not behave as expected. This could open a new frontier in scientific ML: the use of explainability as a pathway to formal certification and auditing. XAI provides a mechanism to assess whether the reasoning of a model is aligned with known physics, engineering constraints, or established domain mechanisms. Attribution tools such as saliency maps, together with causal-discovery frameworks where appropriate, can indicate whether an AI system appears to rely on physically meaningful features rather than spurious correlations. This is especially critical for rare but high-impact events, such as mechanical failures or unstable aerodynamic regimes, where small precursors may carry disproportionate influence on safety. By interrogating internal representations, XAI enables scientists and engineers to verify that models use appropriate physical concepts, respect invariances, and behave consistently under perturbations. In this sense, explainability becomes an analogue to structural inspection: it clarifies why a model behaves as it does, not merely how well it behaves on historical tests (i.e., its accuracy). If the model is able to satisfy known concepts, it is also more likely to generalize to unseen scenarios or observations because it might have learned patterns aligned with the underlying mechanisms leading to a given outcome, rather than a spurious input-output map. Generalizability is frequently tied to reduced ML-model “hallucinations”. This is the case for recent hybrid physics-AI models117 and large foundation models with physical constraints. Of course, one may argue that if we had a perfect model, we would not require such an understanding of its internal mechanisms for certification and auditing purposes, since the model would never fail. Yet, this is a rather utopian view of current state-of-the-art ML and more generally of the engineering and scientific world. And it does raise other and more profound questions of human and AI co-existence118.
A certification-oriented XAI framework would integrate three complementary pillars. First, physics-grounded explainability, whereby explanations are evaluated directly against conservation laws, stability properties, domain-specific concepts, or empirical scaling relations. Second, stress-testing via interpretable diagnostics, where distribution shifts, out-of-domain behavior, and extreme-event responses are analysed through explanation-based stability metrics. These diagnostics can reveal failure modes long before they appear in conventional performance scores. Third, explanation-driven uncertainty quantification, where inconsistencies in attribution patterns serve as indicators of epistemic uncertainty. When these elements are combined, they provide an interpretable audit trail that regulators and domain experts can examine, analogous to verification and validation (V&V) frameworks used in engineering certification.
Our view is that explainability is a core scientific instrument for certifying and auditing AI systems. It provides transparency about internal mechanisms, facilitates the identification of unphysical behaviors, and guides model redesign toward more robust and stable architectures. By coupling XAI methodologies with physics-based constraints, hybrid modeling, and rigorous V&V principles, it becomes possible to envision a future where AI components in climate models, structural-dynamics solvers, or autonomous engineering platforms can be certified with the same rigor as traditional numerical models. In medicine, explainability can be used as an AI colleague that explains its decision to its human counterpart, while the human takes the final decision more confidently, and with a transparent auditing trail119. However, in such domains, where governing equations are unavailable or incomplete, interventional validation through randomized controlled trials remains the primary pathway for certifying causal claims; explainability in this context serves as a hypothesis-generation and decision-support tool, not as a substitute for experimental validation.
Such a framework would accelerate the safe integration of AI across science and engineering, enabling regulators, researchers, and industry partners to move from trust by performance to trust by understanding. This transition is essential for unlocking the full potential of AI-enabled discovery and ensuring that AI-driven predictions and decisions remain reliable, transparent, and scientifically grounded across the entire operational spectrum, especially in safety-critical applications, where failure means significant liabilities to the parties affected120.
Discussion and outlook
This Perspective has argued that explainable artificial intelligence provides a unifying framework for learning from machine-learned representations that already exceed human performance in specific tasks. Across discovery, optimization and certification, explainability emerges as a tool that enables humans to inspect model-internal structure, generate mechanistic and causal hypotheses, generalize beyond observed data and establish trust in high-stakes scientific and engineering applications. While these domains differ in objectives, acceptable risk and modes of validation, they share a common challenge: translating high-dimensional, machine-internal representations into forms of understanding that are meaningful and actionable for humans.
A first fundamental challenge concerns the intuitiveness of explanations. Not all explanations that are mathematically faithful are accessible to human experts. Attribution maps, latent variables, or causal graphs may be correct yet fail to align with the domain concepts, scales, or abstractions used in scientific reasoning. This mismatch poses a practical limit for certification and adoption: if explanations cannot be interpreted by regulators, engineers, or scientists, they cannot serve as a basis for accountability or decision making121. Intuitiveness, however, should not be confused with simplicity. This concept reflects whether explanations can be composed, contextualized, and related to known concepts. This places an important constraint on XAI research: explanations must be evaluated not only for faithfulness to the model, but also for their usability by humans in specific scientific and engineering contexts.
A second unifying theme is the role of scientific understanding. Recent philosophical and methodological work has emphasized that understanding is achieved when a theory allows reliable reasoning across contexts without complete computation122. In this sense, understanding is inseparable from abstraction: once the key mechanisms are identified, humans can anticipate system behavior, design interventions, or reason without resolving the complete problem. This perspective offers a powerful lens for learning from the learners. If an ML model has internalized abstractions that enable strong generalization or efficient control, then extracting those abstractions allows humans to use part of the ML-based understanding. In other words, explainable AI can be a mechanism for transferring abstraction from machines to humans, and not simply justifying individual predictions.
Causal reasoning remains important for such a transfer, but only after the distinction between model-level and system-level causality is made. Across all three domains, XAI can indicate whether a model has captured relationships that appear stable under perturbations or interventions in the data or learned representation. In discovery, this generates candidate mechanisms; in optimization, it suggests interventions to test; and in certification, it helps diagnose potential failure modes. Whether these relationships reflect the physical system depends on the representativeness of the data, the adequacy and calibration of the model, the incorporation of domain constraints and independent validation through targeted simulations or experiments. Establishing when a learned model or latent space is sufficiently faithful to support stronger system-level causal claims remains an open research question.
Another cross-cutting issue is the tension between performance and transparency. Highly expressive models often rely on representations that are efficient for machines but unintuitive for humans. In this article, we propose that the explanations should operate at the level of mechanisms, invariances, and causal relations that matter for the task at hand. This perspective reframes explainability as a multi-level concept. A model may remain opaque internally while still yielding explanations that are sufficient for scientific insight, design decisions, or certification requirements. The appropriate level of explanation, therefore, depends on risk, context, and intended use, reinforcing the need for domain-specific standards rather than universal interpretability metrics.
Looking forward, several research directions appear particularly promising. First, there is a need for validation frameworks for explanations that assess model faithfulness, stability under perturbations, consistency across scales and, where causal interpretations are proposed, agreement with independent interventions or domain constraints. Second, scalable methods for causal discovery in learned latent spaces must be further developed, particularly for spatiotemporal and multi-physics systems. To this end, a related challenge is identifiability: causal direction cannot generally be determined from observational data alone without additional assumptions, and non-unique latent representations may yield different causal graphs8,9. Physical constraints, temporal structure and interventional data provide partial remedies, but formal identifiability guarantees for scientific-ML latent spaces remain an open problem. Recent work on physical causal testbeds, such as the Causal Chambers of Gamella et al.123, illustrates how quickly causal discovery algorithms can fail when applied to real physical systems, underscoring the need for intervention-based validation of any causal structure inferred from learned representations. Third, human-AI interaction deserves greater attention: explanations are not static artifacts but part of an iterative dialog in which humans refine questions, constraints, and abstractions.
An important caveat applies throughout this Perspective: the utility of any explainability analysis is bounded by the quality of the underlying model. If the model has not captured the relevant dynamics, whether due to limited training data, insufficient capacity or poor generalization, explanations will reflect the limitations of the model rather than meaningful physical structure. The proposed workflow is therefore most effective when applied to models that have been independently validated within a well-characterized domain of applicability. Outside that domain, XAI can still reveal internal model behavior and flag potential failure modes, but the resulting explanations should not be over-interpreted as physical (or causal) insight.
Progress in one domain will continue to inform the others. Tools developed for extracting governing equations can strengthen certification by revealing non-physical behavior; optimization studies can expose the limits of explanation-based control; and certification requirements can constrain model design in ways that ultimately improve scientific insight. Learning from the learners is therefore not a unidirectional process but a feedback loop: machines learn from data, humans learn from machines, and both co-evolve towards models that are understandable, reliable, and aligned with human values. In this emerging paradigm, agentic-AI systems that combine foundation models with XAI, mechanistic interpretability, interpretable scientific ML, causal reasoning and domain validation can yield a new framework for accelerated and autonomous scientific discovery and design.
References
-
Jumper, J. et al. Highly accurate protein structure prediction with AlphaFold. Nature596, 583–589 (2021).
-
Guastoni, L., Rabault, J., Schlatter, P., Azizpour, H. & Vinuesa, R. Deep reinforcement learning for turbulent drag reduction in channel flows. Eur. Phys. J. E46, 27 (2023).
-
Lundberg, S. M. & Lee, S.-I. A unified approach to interpreting model predictions. Advances in Neural Information Processing Systems30, (2017).
-
Rudin, C. Stop explaining black box machine learning models for high-stakes decisions and use interpretable models instead. Nat. Mach. Intell.1, 206–215 (2019).
-
Camps-Valls, G. et al. Discovering causal relations and equations from data. Phys. Rep.1044, 1–68 (2023).
-
Carloni, G., Berti, A. & Colantonio, S. The role of causality in explainable artificial intelligence. WIREs Data Mining Knowl Discov.15, e70015 (2025).
-
Cremades, A., Hoyas, S. & Vinuesa, R. Classically studied coherent structures only paint a partial picture of wall-bounded turbulence. Nat. Commun. (2025).
-
Pearl, J. Causality (Cambridge University Press, 2009).
-
Peters, J., Janzing, D. & Scholkopf, B. Elements of Causal Inference: Foundations and Learning Algorithms. (MIT Press, 2017).
-
Martínez-Sánchez, A., Arranz, G. & Lozano-Durán, A. Decomposing causality into its synergistic, unique, and redundant components. Nat. Commun.15, 9296 (2024).
-
Sundararajan, M., Taly, A. & Yan, Q. Axiomatic attribution for deep networks. Proc. 34th Int. Conf. Mach. Learn.70, 3319–3328 (2017).
-
Schölkopf, B. et al. On causal and anticausal learning. CML’12: Proceedings of the 29th International Coference on International Conference on Machine Learning. 459–466 (2012).
-
Peters, J., Bühlmann, P. & Meinshausen, N. Causal inference by using invariant prediction: identification and confidence intervals. J. R. Stat. Soc. Ser. B: Stat. Methodol.78, 947–1012 (2016).
-
Bühlmann, P. Invariance, causality and robustness. Stat. Sci.35, 404–426 (2020).
-
Schölkopf, B. Causality for machine learning. Probabilistic and causal inference: The works of Judea Pearl. 765–804 (2022).
-
Schölkopf, B. et al. Toward causal representation learning. Proc. IEEE109, 612–634 (2021).
-
Binkyte, R. et al. Trustworthy AI suffers from invariance conflicts, and causality is the solution. Preprint at arXivhttps://doi.org/10.48550/arXiv.2605.02640 (2026).
-
Wei, J. et al. Xai4extremes: An interpretable machine learning framework for understanding extreme-weather precursors under climate change. Tackling Climate Change with Machine Learning (ICLR. 2025).
-
Camps-Valls, G. et al. Artificial intelligence for modeling and understanding extreme weather and climate events. Nat. Commun.16, 1919 (2025).
-
Yang, L. et al. Diffusion models: a comprehensive survey of methods and applications. ACM Comput. Surv.56, 1–39 (2023).
-
Ameisen, E. et al. Circuit tracing: revealing computational graphs in language models. Transformer Circuits Thread (2025).
-
Mengaldo, G. Explain the black box for the sake of science: the scientific method in the era of generative artificial intelligence. Preprint at arXivhttps://doi.org/10.48550/arXiv.2406.10557 (2024).
-
Turbé, H., Bjelogrlic, M., Lovis, C. & Mengaldo, G. Evaluation of post-hoc interpretability methods in time-series classification. Nat. Mach. Intell.5, 250–260 (2023).
-
Wei, J., Turbé, H. & Mengaldo, G. Revisiting the robustness of post-hoc interpretability methods. Preprint at arXivhttps://doi.org/10.48550/arXiv:2407.19683 (2024).
-
Bommer, P. L., Kretschmer, M., Hedström, A., Bareeva, D. & Höhne, M. M.-C. Finding the right XAI method—a guide for the evaluation and ranking of explainable AI methods in climate science. Artif. Intell. Earth Syst.3, e230074 (2024).
-
Mamalakis, A., Barnes, E. A. & Ebert-Uphoff, I. Investigation of the fidelity of explainable artificial intelligence methods in applications of convolutional neural networks in geoscience. Artif. Intell. Earth Syst.1, e220012 (2022).
-
Mamalakis, A., Ebert-Uphoff, I. & Barnes, E. A. Neural network attribution methods for problems in geoscience: a novel synthetic benchmark dataset. Environ. Data Sci.https://doi.org/10.1017/eds.2022.7 (2022).
-
Mamalakis, A., Ebert-Uphoff, I. & Barnes, E. A. in Explainable artificial intelligence in meteorology and climate science: Model fine-tuning, calibrating trust, and learning new science. (eds Holzinger, A. et al.) xxAI—Beyond Explainable AI: International Workshop, Held in Conjunction with ICML 2020, July 18, 2020, Vienna, Austria, Revised and Extended Papers Lecture Notes in Computer Science (Springer, Cham, 2022).
-
Brunton, S. L., Proctor, J. L. & Kutz, J. N. Discovering governing equations from data by sparse identification of nonlinear dynamical systems. Proc. Natl. Acad. Sci.113, 3932–3937 (2016).
Article
ADS
MathSciNet
CAS
PubMed
PubMed Central
Google Scholar -
Cranmer, M. Interpretable machine learning for science with PySR and symbolic regression. Preprint at arXivhttps://doi.org/10.48550/arXiv.2305.01582 (2023).
-
Vinuesa, R. et al. Decoding complexity: how machine learning is redefining scientific discovery. Preprint at Commun. Phys.9, 168 (2026).
-
Noé, F., Tkatchenko, A., Müller, K.-R. & Clementi, C. Machine learning for molecular simulation. Annu. Rev. Phys. Chem.71, 361–390 (2020).
-
Baek, M. & Baker, D. Deep learning and protein structure modeling. Nat. Methods19, 13–14 (2022).
-
Degrave, J. et al. Magnetic control of tokamak plasmas through deep reinforcement learning. Nature602, 414–419 (2022).
-
Tamayo, D. et al. Predicting the long-term stability of compact multiplanet systems. Proc. Natl. Acad. Sci.117, 18194–18205 (2020).
-
Parker, L. et al. Astroclip: a cross-modal foundation model for galaxies. Mon. Not. R. Astron. Soc.531, 4990–5011 (2024).
Article
ADS
CAS
Google Scholar -
Angeloudi, E. et al. The multimodal universe: enabling large-scale machine learning with 100 tb of astronomical scientific data. Adv. Neural Inf. Process. Syst.37, 57841–57913 (2024).
-
Ling, J., Kurzawski, A. & Templeton, J. Reynolds averaged turbulence modelling using deep neural networks with embedded invariance. J. Fluid Mech.807, 155–166 (2016).
-
Loiseau, J.-C. & Brunton, S. L. Constrained sparse Galerkin regression. J. Fluid Mech.838, 42–67 (2018).
-
Fukami, K., Goto, S. & Taira, K. Data-driven nonlinear turbulent flow scaling with Buckingham Pi variables. J. Fluid Mech.984, R4 (2024).
-
Brunton, S. L., Zolman, N., Kutz, J. N. & Fasel, U. Machine learning for sparse nonlinear modeling and control. Annu. Rev. Control Robot. Auton. Syst.8, 127–152 (2025).
-
Bongard, J. & Lipson, H. Automated reverse engineering of nonlinear dynamical systems. Proc. Natl. Acad. Sci.104, 9943–9948 (2007).
-
Schmidt, M. & Lipson, H. Distilling free-form natural laws from experimental data. Science324, 81–85 (2009).
-
Petersen, B. K. Deep symbolic regression: Recovering mathematical expressions from dataarXiv.1912.04871 (2019)
-
Vaddireddy, H. & San, O. Equation discovery using fast function extraction: a deterministic symbolic regression approach. Fluids4, 111 (2019).
-
Udrescu, S.-M. & Tegmark, M. AI Feynman: a physics-inspired method for symbolic regression. Sci. Adv.6, eaay2631 (2020).
-
Zolman, N., Fasel, U., Kutz, J. N. & Brunton, S. L. SINDy-RL: interpretable and efficient model-based reinforcement learning. Nat. Commun.16, 10714 (2025).
-
Kaptanoglu, A. A., Callaham, J. L., Hansen, C. J., Aravkin, A. & Brunton, S. L. Promoting global stability in data-driven models of quadratic nonlinear dynamics. Phys. Rev. Fluids6, 094401 (2021).
-
Otto, S. E., Zolman, N., Kutz, J. N. & Brunton, S. L. A unified framework to enforce, discover, and promote symmetry in machine learning. J. Mach. Learn. Res.26, 1–83 (2025).
-
Rudy, S. H., Brunton, S. L., Proctor, J. L. & Kutz, J. N. Data-driven discovery of partial differential equations. Sci. Adv.3, e1602614 (2017).
-
Schaeffer, H. Learning partial differential equations20160446 (2017)
-
Messenger, D. A. & Bortz, D. M. Weak sindy for partial differential equations. J. Comput. Phys.https://doi.org/10.1016/j.jcp.2021.110525 (2021).
-
Reinbold, P. A., Kageorge, L. M., Schatz, M. F. & Grigoriev, R. O. Robust learning from noisy, incomplete, high-dimensional experimental data1–8 (2021)
-
Fasel, U., Kutz, J. N., Brunton, B. W. & Brunton, S. L. Ensemble-sindy: Robust sparse model discovery in the low-data, high-noise limit, with active learning and control. Proc. R. Soc. A. 478, 20210904 (2022).
-
Beetham, S. & Capecelatro, J. Formulating turbulence closures using sparse regression with embedded form invariance. Phys. Rev. Fluids5, 084611 (2020).
-
Beetham, S., Fox, R. O. & Capecelatro, J. Sparse identification of multiphase turbulence closures for coupled fluid–particle flows. Journal of Fluid Mechanicshttps://doi.org/10.1017/jfm.2021.53 (2021).
-
Schmelzer, M., Dwight, R. P. & Cinnella, P. Discovery of algebraic Reynolds-stress models using sparse symbolic regression. Flow, Turbulence Combust.104, 579–603 (2020).
-
Alves, E. P. & Fiuza, F. Data-driven discovery of reduced plasma physics models from fully-kinetic simulations. Phys. Rev. Research4, 033192 (2022).
-
Supekar, R. et al. Learning hydrodynamic equations for active matter from particle simulations and experiments. Proc. Natl. Acad. Sci.120, e2206994120 (2023).
-
Zanna, L. & Bolton, T. Data-driven equation discovery of ocean mesoscale closures. Geophys. Res. Lett.47, e2020GL088376 (2020).
-
Long, Z., Lu, Y. & Dong, B. Pde-net 2.0: Learning PDEs from data with a numeric-symbolic hybrid deep network. J. Comput. Phys.399, 108925 (2019).
-
Kingma, D. P. & Welling, M. Auto-encoding variational Bayes. Preprint at arXivhttps://doi.org/10.48550/arXiv.1312.6114 (2013).
-
Lusch, B., Kutz, J. N. & Brunton, S. L. Deep learning for universal linear embeddings of nonlinear dynamics. Nat. Commun.9, 4950 (2018).
-
Champion, K., Lusch, B., Kutz, J. N. & Brunton, S. L. Data-driven discovery of coordinates and governing equations. Proc. Natl. Acad. Sci.116, 22445–22451 (2019).
-
Lee, K. & Carlberg, K. T. Model reduction of dynamical systems on nonlinear manifolds using deep convolutional autoencoders. J. Comput. Phys.404, 108973 (2020).
-
Conti, P., Gobat, G., Fresca, S., Manzoni, A. & Frangi, A. Reduced order modeling of parametrized systems through autoencoders and sindy approach: continuation of periodic solutions. Comput. Methods Appl. Mech. Eng.411, 116072 (2023).
-
Mounayer, J., Rodriguez, S., Ghnatios, C., Farhat, C. & Chinesta, F. Rank reduction autoencoders–enhancing interpolation on nonlinear manifolds. Preprint at arXivhttps://doi.org/10.48550/arXiv.2405.13980 (2024).
-
Brunton, S. L. & Kutz, J. N.Data-Driven Science and Engineering: Machine Learning, Dynamical Systems, and Control 2nd edn (Cambridge University Press, 2022).
-
Bakarji, J., Champion, K., Nathan Kutz, J. & Brunton, S. L. Discovering governing equations from partial measurements with deep delay autoencoders. Proc. R. Soc. A479, 20230422 (2023).
-
Takeishi, N., Kawahara, Y. & Yairi, T. Learning Koopman invariant subspaces for dynamic mode decomposition (2017).
-
Yeung, E., Kundu, S. & Hodas, N. Learning deep neural network representations for Koopman operators of nonlinear dynamical systems. In Proccedings of American Control Conference (ACC) (Philadelphia, PA, USA, 2019).
-
Wehmeyer, C. & Noé, F. Time-lagged autoencoders: Deep learning of slow collective variables for molecular kinetics. J. Chem. Phys.148, 1–9 (2018).
-
Mardt, A., Pasquali, L., Wu, H. & Noé, F. VAMPnets: deep learning of molecular kinetics. Nat. Commun.https://doi.org/10.1038/s41467-017-02388-1 (2018).
-
Otto, S. E. & Rowley, C. W. Linearly-recurrent autoencoder networks for learning dynamics. SIAM J. Appl. Dyn. Syst.18, 558–593 (2019).
-
Locatello, F. et al. Challenging common assumptions in the unsupervised learning of disentangled representations, 4114–4124 (PMLR, 2019).
-
Lachapelle, S. et al. Nonparametric partial disentanglement temporal dependencies. J. Mach. Learn. Res.27, 1–90 (2026)
-
Lippe, P. et al. Citris: Causal identifiability from temporal intervened sequences, 13557–13603 (PMLR, 2022).
-
Cranmer, M. et al. Disentangled sparsity networks for explainable AI. (2021).
-
Noé, F., Olsson, S., Köhler, J. & Wu, H. Boltzmann generators: Sampling equilibrium states of many-body systems with deep learning. Science365, eaaw1147 (2019).
-
Greydanus, S., Dzamba, M. & Yosinski, J. Hamiltonian neural networks. Adv. Neural Inf. Process. Syst.32, 15379–15389 (2019).
-
Cranmer, M. et al. Lagrangian neural networks. Preprint at arXivhttps://doi.org/10.48550/arXiv.2003.04630 (2020).
-
Miller, B. K., Geiger, M., Smidt, T. E. & Noé, F. Relevance of rotationally equivariant convolutions for predicting molecular properties. Preprint at arXivhttps://doi.org/10.48550/arXiv.2008.08461 (2020).
-
Batzner, S. et al. E (3)-equivariant graph neural networks for data-efficient and accurate interatomic potentials. Nat. Commun.13, 2453 (2022).
-
Brandstetter, J., Berg, R. v. d., Welling, M. & Gupta, J. K. Clifford neural layers for PDE modeling. In International Conference on Learning Representationshttps://mlanthology.org/iclr/2023/brandstetter2023iclr-clifford/ (2023).
-
Brandstetter, J., Welling, M. & Worrall, D. E. Lie point symmetry data augmentation for neural PDE solvers. International Conference on Machine Learning 2241–2256 (2022).
-
Du, P., Parikh, M. H., Fan, X., Liu, X. & Wang, J. Conditional neural field latent diffusion model for generating spatiotemporal turbulence. Nat. Commun.15, 10416 (2024).
-
Solera-Rico, A. et al. β-Variational autoencoders and transformers for reduced-order modelling of fluid flows. Nat. Commun.15, 1361 (2024).
-
Mnih, V. et al. Human-level control through deep reinforcement learning. Nature518, 529–533 (2015).
-
Lillicrap, T. P. et al. Continuous control with deep reinforcement learning. Preprint at arXivhttps://doi.org/10.48550/arXiv.1509.02971 (2015).
-
Erion, G., Janizek, J. D., Sturmfels, P., Lundberg, S. M. & Lee, S.-I. Improving performance of deep learning models with axiomatic attribution priors and expected gradients. Nat. Mach. Intell.3, 620–631 (2021).
-
Martins, J. R. R. A. & Lambe, A. B. Multidisciplinary design optimization: a survey of architectures. AIAA J.51, 2049–2075 (2013).
-
Jameson, A. Aerodynamic design
-
Shapley, L. S. et al. A value for n-person games (1953).
-
Simonyan, K., Vedaldi, A. & Zisserman, A. Deep inside convolutional networks: Visualizing image classification models and saliency maps. Preprint atarXivhttps://doi.org/10.48550/arXiv.1312.6034 (2013).
-
Cremades, A. et al. Identifying regions of importance in wall-bounded turbulence through explainable deep learning. Nat. Commun.15, 3864 (2024).
-
Larrañaga, A., Sandberg, R. D., Martínez, J. & Porteiro, J. On the machine learning-assisted identification of the fundamental parameters of nonstandard microfin arrays to assess their heat transfer performance. Eng. Appl. Artif. Intell.136, 108945 (2024).
-
Zhao, P. et al. A machine learning and CFD modeling hybrid approach for predicting real-time heat transfer during cokemaking processes. Fuel373, 132273 (2024).
-
Singh, S., Suman, S., Kumar, M. & Mitra, S. Ann model for prediction of thermo-hydraulic performance of a solar air heater with vertical cylindrical ribs. Energy Rep.8, 585–592 (2022).
-
Verma, S., Novati, G. & Koumoutsakos, P. Efficient collective swimming by harnessing vortices through deep reinforcement learning. Proc. Natl. Acad. Sci. USA. 115, 5849–5854 (2018).
-
Vishwasrao, A. et al. Diff-sport: Diffusion-based sensor placement optimization and reconstruction of turbulent flows in urban environments. Preprint at arXivhttps://doi.org/10.48550/arXiv.2506.00214 (2025).
-
Beneitez, M., Cremades, A., Guastoni, L. & Vinuesa, R. Improving turbulence control through explainable deep learning. Preprint atarXivhttps://doi.org/10.48550/arXiv.2504.02354 (2025).
-
Heaton, H. & Wu Fung, S. Explainable AI
-
Murray, B. et al. Explainable AI for understanding decisions and data-driven optimization of the Choquet integral. 2018 IEEE International Conference on Fuzzy Systems. (FUZZ-IEEE) (2018).
-
Shen, Y., Huang, W., Wang, Z. & Xu, D. F. An automatic visible explainer of geometric knowledge for aeroshape design optimization based on SHAP. Aerosp. Sci. Technol.127, 107800 (2022).
-
Hinton, G. E. & Salakhutdinov, R. R. Reducing the dimensionality of data with neural networks. Science313, 504–507 (2006).
-
Higgins, I. et al. beta-VAE: learning basic visual concepts with a constrained variational framework. International Conference on Learning Representations (ICLR) (2017).
-
Arranz, G. & Lozano-Durán, A. Informative and non-informative decomposition of turbulent flow fields. J. Fluid Mech.1000, A95 (2024).
-
Chen, M. et al. Explainable machine learning model for load-deformation correlation in long-span suspension bridges using XGBoost-SHAP. Dev. Built Environ.20, 100569 (2024).
-
Chung, W. T., Mishra, A. A. & Ihme, M. Interpretable data-driven methods for subgrid-scale closure in les for transcritical LOX/GCH4 combustion. Combust. Flame239, 111758 (2022).
-
Sanchis-Agudo, M. et al. Easy attention: A simple attention mechanism for temporal predictions with transformers. APL Comput. Phys.1, 016104 (2025).
-
Bommasani, R. et al. On the opportunities and risks of foundation models. Preprint at arXivhttps://doi.org/10.48550/arXiv.2108.07258 (2022).
-
Gottweis, J. et al. Towards an AI co-scientist. Nature655, 487–496 (2026).
-
Vinuesa, R., Manchón, P., Hoyas, S. & García-Martínez, J. Balancing ai and human insights in scientific discovery: Challenges and guidelines. Innovation7, 101144 (2026).
-
Wadell, A. et al. Foundation models for discovery and exploration in chemical space. Preprint at arXivhttps://doi.org/10.48550/arXiv.2510.18900 (2025).
-
Carreon, A., Sharma, V. & Raman, V. Automated design optimizationivhttps://doi.org/10.48550/arXiv.2511.22651 (2025)
-
Administration, F. A. Summary of the FAA’s Review of the Boeing 737MAX. Tech. Rep. https://www.faa.gov/sites/faa.gov/files/2022-08/737_RTS_Summary.pdf (2020).
-
Wang, X. et al. Condensnet: Enabling stable long-term climate simulationsts. npj Climate and Atmospheric Science (2025)
-
Bostrom, N.Superintelligence: Paths, Dangers, Strategies (Oxford University Press, 2014).
-
Wei, J., Verona, E., Bertolini, A. & Mengaldo, G. Explainability matters: The effect of liability rules on the healthcare sector. Preprint at arXivhttps://doi.org/10.48550/arXiv.2509.17334 (2025).
-
Vinuesa, R. & Sirmacek, B. Interpretable deep-learning models to help achieve the Sustainable Development Goals. Nat. Mach. Intell.3, 926 (2021).
-
Selbst, A. D. & Barocas, S. The intuitive appeal of explainable machines. Fordham L. Rev.87, 1085–1139 (2018).
-
Krenn, M. et al. On scientific understanding with artificial intelligence. Nat. Rev. Phys.4, 761–769 (2022).
-
Gamella, J. L., Peters, J. & Bühlmann, P. Causal chambers as a real-world physical testbed for AI methodology. Nat. Mach. Intell.7, 107–118 (2025).
Acknowledgments
Open AI’s GPT-5.5 was used to generate some of the images in Figs. 1 and 3. It was also used to polish the text, and all the edits were thoroughly revised by the authors. The scientific content, discussions and conclusions were entirely produced by the authors.
Funding
RV acknowledges funding from the University of Michigan. SLB acknowledges support from The Boeing Company and the National Science Foundation AI Institute in Dynamic Systems (grant number 2112085).
Authors and Affiliations
Contributions
All the authors (R.V., S.L.B. and G.M.) contributed equally to the conceptualization, idea development and writing process of this manuscript.
Ethics declarations
Competing interests
The authors declare no competing interests.
Peer review
Peer review information
Nature Communications thanks Antonios Mamalakis and the other anonymous reviewer(s) for their contribution to the peer review of this work.
Additional information
Publisher’s note Springer Nature remains neutral with regard to jurisdictional claims in published maps and institutional affiliations.
Rights and permissions
Open Access This article is licensed under a Creative Commons Attribution-NonCommercial-NoDerivatives 4.0 International License, which permits any non-commercial use, sharing, distribution and reproduction in any medium or format, as long as you give appropriate credit to the original author(s) and the source, provide a link to the Creative Commons licence, and indicate if you modified the licensed material. You do not have permission under this licence to share adapted material derived from this article or parts of it. The images or other third party material in this article are included in the article’s Creative Commons licence, unless indicated otherwise in a credit line to the material. If material is not included in the article’s Creative Commons licence and your intended use is not permitted by statutory regulation or exceeds the permitted use, you will need to obtain permission directly from the copyright holder. To view a copy of this licence, visit http://creativecommons.org/licenses/by-nc-nd/4.0/.
About this article
Cite this article
Vinuesa, R., Brunton, S.L. & Mengaldo, G. Explainable AI: learning from the learners.
Nat Commun17, 7933 (2026). https://doi.org/10.1038/s41467-026-76359-w
-
Version of record:06 August 2026
-
DOI
:https://doi.org/10.1038/s41467-026-76359-w
